A better broadcast shift handover with agentic AI
At 06:55, a broadcast shift handover says the overnight fault is resolved. The ticket is closed, the channel is on air, and the incoming operator has a live programme starting in 35 minutes. Buried in the logs, however, is another failure after the ticket was closed. Who checked that?
A handover agent could investigate that gap before responsibility changes hands. Its value would come from connecting evidence across systems, pursuing unanswered questions and keeping recovery work visible. This article describes a proposed operational workflow, rather than an announced Evrideo product feature.
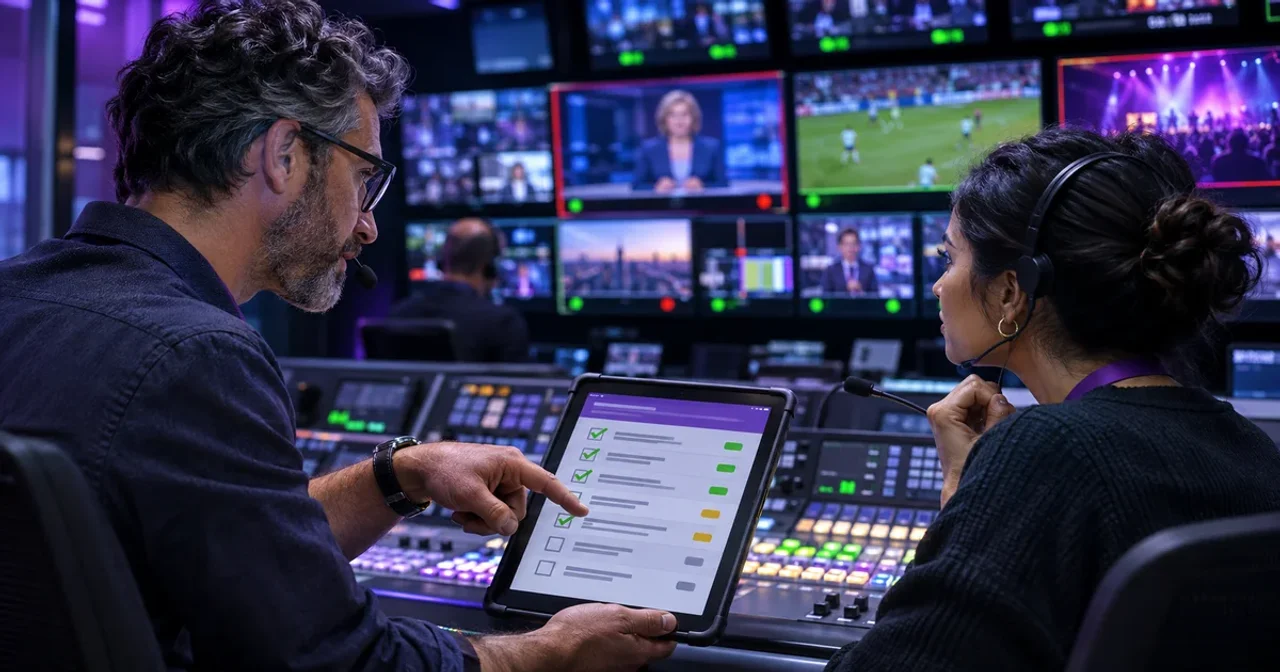
What a broadcast shift handover needs
Good handovers already depend on preparation, conversation and cross-checking. The UK’s Health and Safety Executive describes those three stages and recommends combining written and verbal communication. Its guidance concerns industrial operations, but the principle transfers well to a broadcast control room.
The incoming team needs the current service state, deviations from normal operation and the next decision. A temporary backup route might be delivering perfectly while leaving the channel without its usual redundancy. That detail belongs near the top of the brief.
For an active incident, responsibility should transfer explicitly. Google’s SRE incident guidance calls for a living incident document and an acknowledged handoff. Routine shifts need a lighter process, but an unresolved on-air fault deserves a named owner who accepts it.
Where an agent earns its place
Required fields, reminder timers and playlist-to-MAM checks are established automation tasks. Keep those checks deterministic. A language model adds cost and uncertainty when the rule is already precise.
An agent becomes useful when the next investigation step depends on what it discovers. It can compare a ticket with a later alarm, check whether both refer to the same asset version, retrieve the relevant playback evidence, then ask a targeted question if the records still disagree.
That involves several bounded steps across systems. Each conclusion should link to its evidence, with timestamps and unresolved uncertainty visible to the operator.
The agent can revisit the evidence when answers reveal another gap. The operator accepts the resulting handover; the diagram does not authorise automatic changes to the channel.
Follow the contradiction
Consider a hypothetical three-channel broadcaster. At 02:10, an operator replaces a failing programme asset and closes the ticket after a successful preview. At 04:40, a transmission log records another failure under the same programme title. The next scheduled transmission is at 07:30.
An agent should first match asset IDs and versions. The later log might concern the original file, a different regional version or an unrelated event with the same title. A title match alone would produce a poor escalation.
Suppose the later failure concerns the replacement file on a second channel. The agent retrieves the available QC result, checks which version is scheduled and asks the outgoing operator what was tested. A preview on one channel cannot establish successful delivery on every affected output.
The brief can now state the actual gap: the replacement preview passed, a later failure occurred on the second channel, and subsequent recovery remains unverified. It identifies the 07:30 event, links the evidence and proposes a verification task for the incoming operator. Any asset replacement or routing change still follows the broadcaster’s approval process.
Connect the next shift’s dependencies
Now add maintenance on the backup path at 08:00. A temporary workaround that looked acceptable overnight may conflict with that maintenance window.
An agent could connect the incident record to the maintenance plan and ask the duty engineer whether the change should proceed. This requires accurate service identifiers and dependency records. Missing mappings should appear as unknowns; the model must never invent the topology.
Make completion evidence explicit
Give every outstanding action an affected service, named owner, deadline and agreed acceptance check. Record the source links and the time each observation was collected. Separate a proposed action from one that a person has accepted.
- 1Assign and acknowledge
The incoming operator accepts ownership and the next check.
- 2Await verification
Collect the agreed output evidence after the corrective action.
- 3Verify or escalate
Record the result. Missing or stale evidence, or checks showing recovery has failed, keep the action open.
A cleared alarm or closed ticket is one observation. Closure depends on the agreed recovery evidence for the affected service and output.
Set limits on investigation time and tool calls. When evidence is unavailable, the agent should explain what it could not check and escalate to the owner. Endless retries would add noise precisely when the control room needs a decision.
Keep permissions outside the model
Start with read-only access to the operational records needed for the brief. Grant task-writing permissions separately, and require approval for changes affecting playout, routing or schedules.
OWASP’s excessive-agency guidance recommends narrowly scoped tools, least privilege and human approval for high-impact actions. Authorization belongs in the connected systems. A sentence inside a ticket cannot grant an agent permission to switch a live output.
Treat retrieved notes as untrusted evidence: they can contain mistakes or malicious instructions. Log tool calls and resulting updates so an operator can reconstruct how the brief was assembled.
Pilot against real handover failures
Run the agent alongside the existing handover process before allowing it to update operational records. Test closed tickets with later alarms, stale telemetry, missing owners and maintenance conflicts. Include ordinary, uneventful shifts to measure unnecessary escalation.
Score missed contradictions, unsupported claims, incorrect closure recommendations and operator correction effort. NIST’s generative AI risk profile recommends verifying output sources and citations during evaluation and ongoing monitoring. A fluent brief still needs evidence behind it.
A useful broadcast shift handover leaves the incoming team knowing what is running, what remains uncertain and who will check it next. Discuss how that workflow fits your channel operation with Evrideo’s managed services team.
Related Articles
Multilingual channels: an operational checklist
October 28, 2026 · 6 min read
Building a Broadcast-Quality FAST Channel in Under a Day: A Technical Walkthrough
July 1, 2026 · 7 min read
Repurposing Live Sports for Social Without Buying More Rights
September 2, 2026 · 8 min read